Lev Plotkin

Backend & Data Tech Lead
Senior Backend and Data Engineer with 15+ years of experience building distributed systems, data pipelines, and AI-powered applications across cybersecurity, biotech, fintech, and enterprise software. I enjoy working across the full stack - from Kafka and Spark event pipelines to Snowflake data warehouses to LLM-powered services - and I'm always looking for opportunities to experiment with what's new. I care about good engineering, good collaboration, and sharing what I learn along the way.
Portfolio
AI Software Engineer
As an AI Software Engineer at Bonterra, I develop AI solutions that enhance the effectiveness of our extensive network of non-profit organizations and social workers. I integrate autonomous security agents into GitHub Actions and Ruby on Rails CI/CD workflows using Claude, ensuring robust security measures. The pipelines I create continuously scan dependencies, automatically address breaking API changes through self-healing test loops, and mitigate CVE risks, resulting in a more resilient and secure development environment.
Tikal knowledge
Senior Backend & Data Agentic Engineer
I led and contributed to multiple internal AI initiatives at Tikal, focused on agentic systems, LLM-powered applications, and data platforms that drive engineering innovation, knowledge sharing, and internal product development. Working closely with engineering teams and technology leaders, I designed and implemented production-ready AI solutions while leading hackathon teams and promoting AI engineering best practices across the organization.
Key initiatives included:
- Designed and implemented a multi-source data platform using Airbyte, integrating CRM, Google Sheets, MySQL, S3, and BigQuery to support organization-wide data pipelines.
- Built an AI-powered QA service using LangGraph, enabling intelligent, agent-driven quality assurance workflows.
- Led the development of TechReviewAI, a Generative AI platform that helps developers evaluate software technologies, tools, and libraries through AI-generated insights.
- Initiated and led Tikal's ML Forum, establishing best practices and knowledge sharing around AI and machine learning across engineering teams.
- Led the development of QuestGen, a multi-agent AI system that powers dynamic storytelling and gameplay for an interactive D&D experience.
- Led the development of TechNavigator, an AI-powered technology intelligence platform that automates the pipeline from technology signal detection to Israeli Tech Radar publication, grounded in real-world evidence and expert validation.
Gong
Senior Data and Backend Developer
As a member of the Data Platform team, I contributed to modernizing the data pipeline infrastructure and enforcing data governance across the warehouse at scale. Refactored and redesigned core dbt models ingesting CDC events via Debezium, implementing robust handling of deletes, deduplication logic, and Snowflake Streams to enable efficient incremental processing.
Developed a Java Spring Boot service responsible for data governance enforcement, including data retention policy management and full customer offboarding workflows
Tech stack: dbt, Snowflake, Java Spring Boot, PostgreSQL, AWS
Senior Backend Developer
Verbit is a leading provider of AI-driven transcription and captioning solutions.
This project aimed to enhance Verbit's offerings by introducing intelligent search capabilities and providing valuable insights, particularly for legal, education, and media industries.
As an Insights and Search team member, I contributed to developing services that utilize LLMs to extract actionable insights from audio and enable seamless search across user-provided documents alongside transcriptions.
Developed solutions using Python, AWS (Lambda, API Gateway, Bedrock), PostgreSQL, and OpenSearch with vector database integration.
Senior Backend & Data Engineer
BigPanda is an Event Correlation and Automation platform, catering to large-scale and complex IT environments. It integrates, normalizes, and enriches alerts from over 300 monitoring tools, offering capabilities such as Root Cause Analysis and Level-0 Automation to enhance service availability and streamline IT operations for Fortune 1000 companies.
As a team member, I participated in the development of two features:
- Identifying the propagation of security incidents or failures, considering network topology.
My role involved developing integration tests and implementing additional features, such as the dynamic configuration service
Stack: Java, Spring Boot, AWS Neptune with Cypher, Kubernetes, Test Containers - Identification of similar security incidents or failures for which solutions already exist.
My part involved developing a scheduled process for loading new incidents from Snowflake for further analysis
Stack: Argo Workflows, TypeScript, Kubernetes, Kafka, Snowflake, OpenSearch as Vector Database
Senior Backend Developer
Qualcomm creates semiconductors, software, and services related to wireless technology.
I participated in a joint venture between Qualcomm and BMW within the automotive sector, involving processing data collected from tested vehicles.
Developing with Python, GitHub Actions, Argo Workflow, K8s, AWS (EKS, SQS, S3, EFS ...)

Senior Backend Developer
Lightricks develops creativity tools that enable its users to craft and share visual content on mobile devices. Lightricks integrates advanced technologies from computer vision, computer graphics, and image processing into mobile products.
As an MLOps engineer in the research infrastructure team, I developed and supported services used by research and engineering teams such as model registry, management, validation, benchmarking and building blocks library for researchers.
Developing with Python, FastAPI, Postgres, K8s, BigQuery, Redash

Senior Backend Developer
An end-to-end single-cell platform enables high-resolution profiling of the immune system at an industrial scale, generating biological insights that accelerate R&D and power novel discoveries.
My major task at Immunai was to implement a datasets metadata managing solution based on CKAN.
The feature was to develop from scratch and delivered to production using GCP and Serverless.
Chosen stack is Python, microservices-based, Google data catalog was tested and rejected after POC (it doesn't fit the requirements)
In addition, I made a research and initial implementation for processing sparse data in Spark (pyspark runs scala UDF). Another research was comparison of Snowflake and Databriks for building a company Data lake

Senior Backend and Big Data Developer
SentinelOne secures enterprises with the autonomous cybersecurity platform. Endpoint. Cloud. IoT. XDR My role as a team member was to take a part in design and implementation features in the BigData domain. Features: *export clients data from internal systems (including onboarding service aside with pipeline) *GDPR support (including developing CLI tool and integrate it to Jenkins job) *BI pipelines report the internal system usage for monitoring and finance (using Spark Kubernetes operator for scheduling jobs) Challenge was to provide a full cycle solution including deployment with IaC approach from scratch to production in a short time. The solution had to be performant and scalable enough to support events rate like 10M/sec Stack: Spark, Kafka, Scala, K8s, Jenkins, Helm, Python, Postgres, AWS (RDS,S3,Redshift)
Ensilo
Senior Backend and Bif Data Developer
FortiEDR (former enSilo) delivers advanced, real-time threat protection for endpoints both pre and post-infection My role was to design and implement search-engine over the threat events. Architecture for the feature, API, integration, and performance testing. Challenge: to support flexible schema with ad hoc queries. The implementation: middleware application transforms clients requests to internal queries Also manage and configure scheme versions and data lifecycle policy Stack: Elasticsearch, Kafka + Kafka Connect, Java, Spring, K8s, Python, GC

Senior BackEnd Developer
BigID’s Software redefines how enterprises find, analyze and de-Risks Identity data for today’s personal information (PI) protection, privacy and data governance problems. Stack: Node.Js Spring, MongoDB, RabbitMQ, Linux, Docker
Citi
Senior BackEnd Developer
Taking part in Total conduct project ( Citi bank innovation center).
Product used to scan any kind of correspondence ( eg chat or emails) in organization to alert complies about misconducs. My responsibility in this project is to build API exposes the system and support existing pipeline.
Stack: SpringBoot to API Cloudera cluster to pipeline including hive, oozie, spark, hdfs.

Senior Java Developer
Trusteer products help detect and prevent the full range of attack vectors responsible for the majority of online, mobile and cross-channel fraud. I joined the project in Trusteer at very beginning and helped to get it's first version to production I was involved in number of infrastructural tasks including Kafka integration, ssl configuration, license management. Stack: Java, Tomcat, MySQL, Linux, Kafka, RabbitMQ, AWS.
Earnix
Senior Java Developer
Earnix is a software platform for pricing analytics and optimization used by insurance and retail banking organizations. My role was to help integrate the platform with external statistical tools R and H2O. The task had included research and implementation . Also I was involved in data layer migration from EJB2 to JPA as part of Earnix intention to move on from IBM JEE stack to open source. Stack: JEE, Websphere, Oracle/Db2, Windows/Linux.
Seculert
Senior Java Developer
Seculert is a cloud-based cyber security technology company. The company’s technology is designed to detect breaches and Advanced Persistent Threats, attacking networks. My role was to help with OpenDns integration Also I was involved in research task for cross site scripting attack demo including building js client and backend in spring boot. Stack: Spring, RabbitMQ, AWS, Linux.
Latest Articles
How We Predict Future Tech Trends with the Tech Radar
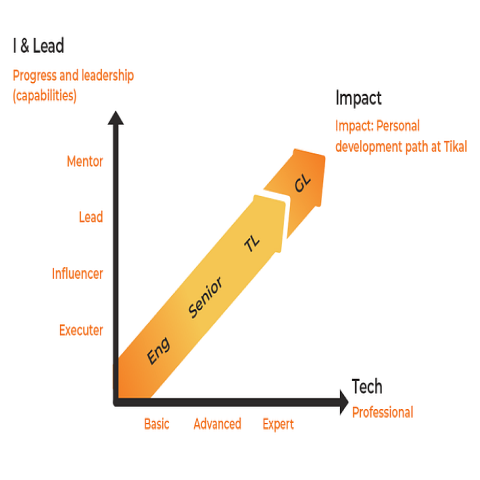
Starting a Roadmap Program in Your Organization
There’s a disease festering in your code
Ready to Tech?
Let us know your tech needs, and we’ll take it from there.